Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the original livestream.
7:14:23Hello
7:14:23Exciting to be here. My name is Frank. I work at Coatue which is a technology investment firm across public and private markets
7:14:30So, in our business, what you really need to do is be able to take high conviction bets
7:14:36on big themes and watch those play out.
7:14:39I think, honestly, a career is the same way.
7:14:42And last year when I joined Coatue, the bet that I wanted to make was I think that agents
7:14:47will have an even bigger impact in investing than they did at coding.
7:14:51I know that's a big statement.
7:14:53We're all here because of the transformative impact that AI has had in coding.
7:14:57But I really believe it strongly.
7:14:59And today I want to talk a little bit about the framework that we use to actually realize
7:15:03that impact.
7:15:05So, at a high level, you can think about a hedge fund as a function that takes in two
7:15:10parameters, context external and context internal, and spits out one tuple.
7:15:17Selection, size, timing.
7:15:20stock, how much, when.
7:15:23And I think this is a good framework to actually ground our work, which is we are trying to
7:15:30solve this compression problem of how do you take all the information in the world and
7:15:35spit out this one simple tuple and the product that we provide is essentially a time series
7:15:41of this tuple that constructs a portfolio.
7:15:44let's start from the top, which is the inputs.
7:15:48simple philosophy.
7:15:49We use our screens, we look at stuff, we do work.
7:15:53Every single thing that a human can see in pixels on the screen, an agent in your building
7:15:57should be able to see via API.
7:15:59The analogy I use is imagine you brought the smartest people ever, the greatest investors
7:16:05alive and you brought them into your company but you gave them a computer without logins
7:16:10to 75% of your services.
7:16:12It's almost immaterial how smart this system is if it doesn't have the tools to actually
7:16:17action that.
7:16:18So the two parts, external context, no surprises here, think the news, prices, filings, all
7:16:27of that should be easily accessible and not via dragging and dropping, copy and pasting,
7:16:33like directly via API.
7:16:36Internal context is just as important, right?
7:16:40So this is your own firm situation.
7:16:42So that might be our current positions, potential liquidity and risk requirements we have around
7:16:47certain names, and past case studies or history with a certain sector or stock or management
7:16:55team.
7:16:56That is all super important.
7:16:58So this is the foundation, and I think, no credit to me, Coatue has been an amazing leader
7:17:03on this for over a decade.
7:17:05It is both technological and cultural.
7:17:07We have an amazing data science team, amazing processes, amazing systems that bring all
7:17:13this in, and just as importantly, we have a culture that is super, super rigorous and
7:17:18built from the ground up to capture all this insight.
7:17:21For decades, we filed every single note about every single trade, about every single decision
7:17:26we made or didn't make about what went well and what didn't go well, and that has poised
7:17:30us to expose us to AI.
7:17:34If you think about it, I probably can't just take all of those things, jam them into a
7:17:39context window and get my magic three numbers and go home.
7:17:44It can't be that easy.
7:17:45You probably have to break down this function a bit further.
7:17:50So maybe the first step is I take in that external and internal context and I gather
7:17:56it.
7:17:57I want to gather it, I want to filter out what is relevant and not relevant.
7:18:01Okay, well, I pulled some news articles about the MBA that probably isn't material to stocks,
7:18:06but this is related to local permitting that might impact data centers.
7:18:13There is a lot of nuance in this gather step.
7:18:17you will see probably the next step is I need to analyze that information and form
7:18:21a view.
7:18:22I need to think about what that means for the markets, public and private, and then
7:18:30I need to take that view and turn it into a decision.
7:18:33A decision object has these three parameters, these three sub pieces.
7:18:39You can see every single step has an input and an output, and the input for the subsequent
7:18:46step is the output that the previous function generated.
7:18:50I think as an engineer, this is a way for me to conceptualize the problem in a way that
7:18:56makes a lot of sense.
7:18:57But even this, it really can't be as simple as writing three functions.
7:19:02So let's just, to really appreciate the scope and understand the full complexity of the
7:19:09problem, let's look into the first step, a tiny sub piece of a tiny sub piece of just
7:19:15gathering information and let's do a case study on interpreting the news.
7:19:21So it's probably no secret to you guys that news from Asia and Korean media outlets has
7:19:29been super important this year because semis, AI, have been a huge, huge theme in the market.
7:19:35Huge theme.
7:19:36And I think this is an area where AI is poised to have a lot of impact.
7:19:41Reading Korean language news better than our completely non-Korean speaking staff.
7:19:48I think I have a good thesis that this might be a good use case.
7:19:51So you can imagine the first step is I have articles.
7:19:57I need to collect the articles.
7:19:59This
7:20:00could be an MCP, this could be a CLI, license the data feeds, clean the data feeds. There are a lot of ways to do this and a lot of dimensions of freedom for how you can even just write this simple piece. How do I chunk it when I pass it to the LLM? Do I want to pull the images as images? Do I want to pull the images and then turn the images into text? There are actually a lot of knobs here.
7:20:24I almost think about those knobs as hyperparameters in a traditional machine learning system.
7:20:30I think about each of these knobs as something for me to tune and optimize against.
7:20:36Obviously, filtration, we talked about it.
7:20:41There are probably Korean NBA fans, right?
7:20:42There is probably a bunch of stuff that is not necessarily material to the names and
7:20:50themes and stocks in our portfolio that really, really matter.
7:20:53So I want to make sure that I filter those out.
7:20:58There is this translate slash extract slash should I summarize, should I extract this
7:21:03into some sort of structured form.
7:21:06Again, so, so many ways to do this, so many ways to experiment, how to expose information
7:21:10to the model, and one of the reasons this is hard is it keeps changing.
7:21:15And obviously checking.
7:21:17Checking our own internal notes, our own internal views, potential conversations we have had,
7:21:22meeting recordings against these things.
7:21:24We actually need to cross-reference those things.
7:21:28Actually the idea of pulling information from disparate sources and cross-referencing them,
7:21:32that's super powerful.
7:21:34So you will see on the right here I have code, LLM, LLM, code, person.
7:21:39There's many, many ways to run these functions.
7:21:42I think about, oh, yeah, and finally, update.
7:21:46We update our views.
7:21:49There are many ways to run these functions.
7:21:52I think of each line as having a runner, and the most obvious one is code.
7:21:58Code is very good.
7:22:00It is fast, it is cheap, it is reliable, so for something like if the prices to earnings
7:22:07ratio is less than 15, I should just use deterministic code for that.
7:22:12Runner number two is statistics, classical machine learning, and you can imagine fitting
7:22:19the line to a regression for a specific pattern, this is very powerful because you can model
7:22:23much more complex relationships than just pure deterministic code.
7:22:28And for even more complex relationships, the reason we are all here, LLMs, AI agents, that's
7:22:34another type of runner.
7:22:36So for something like summarization, that's the state of the art.
7:22:40It's probably totally impossible to build a bunch of if statements that can summarize
7:22:46better than a modern LLM.
7:22:49Of course, people.
7:22:51People are important runners in the system.
7:22:54Imagine a function meeting the management team of a company.
7:22:58I probably don't want to send an LLM or an AI agent in to do that.
7:23:04I probably don't want to send an if statement into that meeting.
7:23:07I think there are many cases where because of judgment and the ability to navigate the
7:23:12real world and all of these things, a person is the best runner for a given piece of the
7:23:16function.
7:23:18I think this is a super, super important point.
7:23:21There is no glory in automating things for the sake of automating things.
7:23:26The goal is not to take as many things and make them LLM as possible for us.
7:23:30The goal is for any given piece of this function, what can I do to maximize absolute quality?
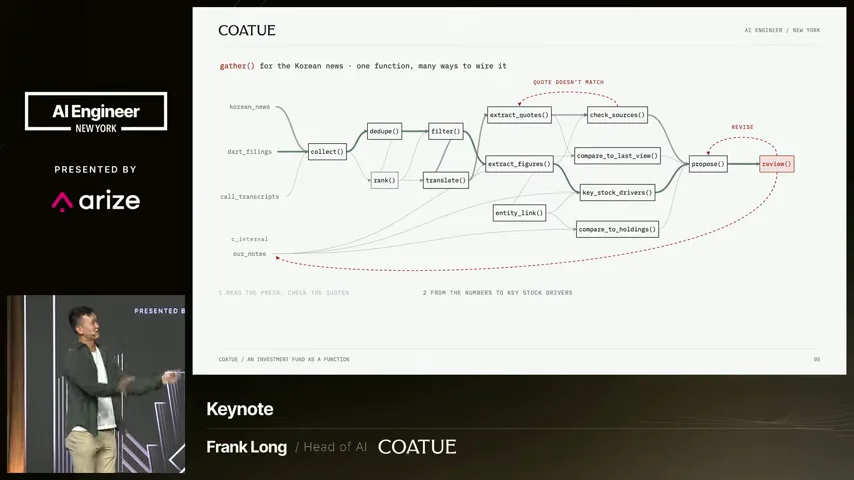
7:23:40And if you actually think about the function, it probably looks something like this.
7:23:44It's probably not just a linear statement of a bunch of different things.
7:23:47There's probably all kinds of branching logic and all kinds of ways to actually fork this.
7:23:52So maybe I want to collect the information and then translate it, and my main goal is
7:23:56to extract quotes and check those against sources to make sure that these are actually
7:24:00the things that people said, and that's my approach.
7:24:03But that might be totally wrong.
7:24:04Maybe what I want to do is I want to de-dupe and then I want to filter and then I want
7:24:09to pull external figures or maybe I want to do something totally different.
7:24:13I actually want to, I'm passing in a note first and I want to find other confirmatory
7:24:17data points or maybe I'm trying to red team.
7:24:20There's a million different ways to configure this.
7:24:22So yet again, more hyperparameters within the control flow, right?
7:24:29So many ways to think about just this very simple problem of pulling, filtering, summarizing
7:24:34aggregating the news for LLMs.
7:24:38And each of these boxes probably has an optimal runner, right?
7:24:45So the optimal runner might be deterministic code for collection, right?
7:24:51I'm pulling last 24 hours for a given source.
7:24:55That's deterministic code.
7:24:57Filtration?
7:25:00models maybe.
7:25:01LLMs?
7:25:02statistical methods, a combination, right?
7:25:06So this probably understates the complexity.
7:25:08The reality is most things are multi-runner.
7:25:10Most things have deterministic code plus LLM plus statistical method or human with LLM
7:25:15in conjunction.
7:25:18reality is it's probably combinatorics between my four buckets and there's even more
7:25:23buckets than that.
7:25:24Because within the LLM category I can tune the model.
7:25:28I can choose big model, small model, medium model.
7:25:31I can tune thinking effort. X high, high, medium, I can tune harness. I can choose the harness. I can
7:25:38choose which skills load with the harness. I can choose which hooks load with the skills.
7:25:41So yet again, more hyperparameters within my search space. I have an absolutely enormous
7:25:46amount of hyperparameters within my search space. And this is just for this one tiny problem, right,
7:25:51of just filtering the news. So the way to think about breaking down these problems is what can I
7:25:58actually compartmentalize in a way that we can understand and evaluate.
7:26:03That's what I'm hill climbing against.
7:26:04Otherwise I'm just tuning these things.
7:26:06I'm okay, that should actually be a machine learning system instead of an LLM.
7:26:10That should be a little model that we train.
7:26:12Oh, no, that shouldn't be a model at all.
7:26:14That should be an if statement.
7:26:15Or, oh, man, LLMs are really, really bad at translating that to portfolio impact.
7:26:20It should really be a human on that step, but they're using a deterministic system to
7:26:25help them search and pull the information.
7:26:27It could be all different things.
7:26:29And if you don't have a north star to hill climb against, you're just kind of, you're
7:26:34just fidgeting around.
7:26:35And I think I cannot convey enough that this is just one tiny thing we do.
7:26:40Imagine every single data source that we pull in, there's probably more than just three
7:26:45transformations to get them to the intermediate output.
7:26:47So the actual graph of Coatue and funds like Coatue, it actually probably looks, oh, not
7:26:54like this.
7:26:56is my screen saver.
7:26:58The actual graph probably looks something like this.
7:27:02It is probably massively complex.
7:27:04In each of those nodes, we just talked about at least ten hyperparameters with at least
7:27:1020 different values for them.
7:27:13So the search space is basically infinite.
7:27:15And figuring out how to actually lay this out in a way that you can comprehend both from
7:27:21technical perspective, but also absorb culturally, organizationally.
7:27:26That is the great challenge of applying AI in investing.
7:27:30And beyond investing, what we're really talking about is creating a state machine that can
7:27:36take information from the world and understand it well enough to make coherent decisions.
7:27:41There's use cases for this far and above, wider than just investment firms, in policy,
7:27:48in non-profits, in drug discovery, in corporate strategy.
7:27:53I think one of the most exciting things for me
7:27:55about being in forums like this
7:27:56is talking to other people in different spaces
7:27:59with different problems that kind of congeal
7:28:02on the same problem space.
7:28:03I'd love to keep talking about this.
7:28:05I'll hang out in the hallway afterwards.
7:28:06Here are my socials.
7:28:08And thank you, everyone, for your time.
7:28:10Thank you.