NOV 5–6, 2026 · SHANGHAI
AI Engineer Shanghai
AI Engineer came to China for the first time. In Shanghai, the people building open models, agents and robots spent two days together, on stage and off.
Shanghai co-organizers
Yuzheng Sun
Superlinear Academy
Shaped the program, invited speakers and connected US and Chinese developer communities.
02days50+speakers≈1,600attendance over two days, organizers’ estimate
Speakers & hosts
Speaker directory ↗58 speakers and hosts

Conference program
Full program archive ↗Open models, agents & infrastructure
09:30-17:50 · UTC+8One stage in the morning. The community panel starts at 13:00; parallel sessions begin at 13:45.
Morning · Main stage09:30-13:00
- 09:35
Welcome
- 09:45
Opening with swyx · Video
About
AI Engineer and Latent Space co-founder swyx opens the conference with a ten-minute video message to the Shanghai audience.
- 10:10
From Models to Working Enterprise Agents
Topic subject to speaker confirmation
Abstract
How models, data, tools and execution boundaries come together in a useful enterprise workflow, and what changes when an agent moves from a demo into ongoing use.
- 10:25
Building Agents: Yesterday, Today, Tomorrow
Abstract
The way agents get built has changed fast. Yesterday: chains and RAG, debugged by eyeballing prompts. Today: tool-calling agents in long loops, kept reliable by traces, datasets built from production failures, and evals that gate releases. Tomorrow (the best teams are already on this): telemetry becomes an interface for the agent. Coding agents pull scored traces from your application, cluster failures, propose fixes and evals, and back-test them. Today a human is still in the loop - in the future perhaps not? I'll cover which signals to expose to agents, where humans should stay in control for now, and what changes when agents become the heaviest readers of your traces.
- 10:45
When we can do anything, do we still know what we want?
Abstract
AI is narrowing the distance between imagination and reality. But as execution becomes easier, doing more, faster becomes the default. We keep producing, reviewing and keeping up, while losing the time to form ideas of our own. If everyone can create but ends up making similar things, what have we actually liberated? Drawing on building tools at Notion and Cursor, creating ryOS, and leaving San Francisco for Taipei, Ryo explores creativity, judgment and autonomy in the AI era. This is not an argument against speed, but a reconsideration of what deserves acceleration, what needs time, and how tools can give life back to people rather than turn life into another production line.
- 10:50
Break
- 11:10
Post-Training at the Frontier: Teaching Open Models to Search and Browse the Web
Abstract
In this session, You.com’s engineering team will share how we post-trained Nemotron 3.5 Lightning, an open-weight 30B model, to become a stronger agent for web search and browsing, using You.com’s real-time web search API, NeMo Gym, supervised fine-tuning, and reinforcement learning. We’ll walk through the technical approach that enabled the team to iterate rapidly. It lifted accuracy on BrowseComp, a benchmark for agentic web search and browsing, from 37% to 45%, while making the agent more efficient with fewer tool calls. We will cover topics ranging from dataset preparation, supervised fine-tuning, and reinforcement learning to the agent harness and search infrastructure that made fast iteration possible. We’ll end with a blueprint for post-training and improving LLMs on real-world search tasks as well as a look at what’s next. This work was done in collaboration with NVIDIA and CoreWeave.
- 11:25
Full-Stack Inference Engineering: Latency, Throughput and Cost
Abstract
Open-source model inference is becoming a compelling option for enterprises, especially those building AI-native applications. Delivering fast, efficient, and reliable inference requires engineering across the full stack, from CUDA kernels and Kubernetes orchestration to quantization, caching, and disaggregation. This talk explores the key design decisions and emerging techniques shaping production inference systems, with practical insights into balancing latency, throughput, cost, and reliability.
- 11:40
Measure the frontier of AI for real world use
Abstract
In this session we will discuss the AI eval products and services Arena provides to help frontier model labs and neo labs measure and improve the performance of their models on the global stage.
- 13:00
Lunch · On your own
Afternoon · Main stage13:00-17:50
- 13:40
Community in the AI era
- AJWaytoAGI · Founder
- KojiCrossing · Founder; Venture Partner, Zhenfund
- Kai Qu42 Chapters · Founder & CEO
Moderator: 高宁 · Linkloud
What makes an AI community worth returning to? Four community founders discuss quality, member contributions, and how conversations turn into projects and lasting collaboration.
- 13:45
Break
- 14:05
From Model Intelligence to Agent Harness: Enabling Long-Horizon Agents
Abstract
As agents take on longer and more complex tasks, sustaining performance becomes a central engineering challenge. Drawing on Step 5 Preview, StepFun’s latest flagship foundation model, and Step Code, its open-source agent harness, this talk explores how models and harnesses work together to help agents stay on track and deliver reliable results in real-world applications.
- 14:25
Dark Factory to Lobsterville: Intent Engineering for Persistent Multiplayer Agents
Abstract
Early 2026 we built the Dark Factory to ship OpenClaw the larget open source agent platform in China and the world, parallel agents running overnight, thousands of commits, pure throughput. It scaled until the output stopped matching what we actually wanted. The bottleneck was intent. Agents produced volume without a durable reason to do any of it. I walk though the city of systems "Lobsterville" we are building at OpenClaw to build OpenClaw. From meat proxies to multiplayer steering and the fundamentals of intent handoff and intent engineering to build the future of AI with agents in a collaborative way.
- 14:30
Break
- 14:50
On-Device AI: Bringing Intelligence Closer to Everyone
Abstract
How can useful AI run directly on phones, PCs and other personal devices rather than depending on the cloud? This talk explores memory bottlenecks in on-device models, using early expert routing and flash streaming to reduce the resident memory footprint. It also covers combining millisecond-scale local decisions with larger on-device models, with examples from headphones, robots and smart glasses.
- 15:10
Kubernetes Is Not Your Sandbox
Abstract
Teams are reaching for Kubernetes to run agent sandboxes, and it's the wrong tool. Kubernetes is built to keep things alive and hold them in a steady state. A sandbox is born, forked, and killed before any of that machinery catches up. The mismatch compounds because the sandbox keeps gaining requirements without shedding any. In eighteen months it went from a fast code-snippet runner, to a stateful box for long-running agents, to ten thousand ephemeral environments that fork for RL rollouts and die in under a second. It has to be all of those at once, a contradiction set no orchestrator was designed to hold. The cost shows up the moment you measure it. We ran the same 50-action bug-fix trajectory across five stacks and got a 12x spread: 12.9s on the fastest, 161.5s on the slowest. The gap isn't compute, it's lifecycle overhead per action. We name every stack and explain the mechanism behind each number.
- 15:30
AI-Native Work at Manus: One Monorepo, Open Tasks
Abstract
Most teams add AI tools to an old workflow. At Manus, we rebuilt our workflow around agents. We keep all our repositories, team rules, and agent skills in one shared workspace, called Manus mono. Mono connects to almost every service in the company, so an agent can write code, run tests, check logs, work with databases, and ship to production from one place. Because of this, anyone in the company can open a PR. Engineers, product managers, designers, and operations staff all fix the bugs they find. On top of this, every task in our team is visible to everyone. This decouples a task from the person who started it. When a task needs information, you send the link to the person who knows, and the task continues after they answer. When a colleague is away, someone else can take over. Open tasks also give us data on how people actually work with AI. In this talk, I share how we built this way of working, what went wrong, and how it changed the way our team collaborates.
- 15:35
Break
- 15:55
Powering open source personal agents with Exa search
Abstract
Power open-source personal agents with Exa’s live web search, Places, weather, and research through a single API.
- 16:15
Your Agent's Memory Is Next Quarter's Training Data
Abstract
An agent that runs twenty steps doesn't issue one retrieval — it issues dozens, and it writes about as much as it reads. The trace it leaves behind is write-heavy, time-ordered, and queried at three granularities: step, span, trajectory. That's the same shape as an RL rollout store. Not similar to — the same. The model labs hit this two years earlier under different names: semantic dedup, decontamination, hard-negative mining. Agent memory and training data are converging on one set of operators — operational writes and analytical scans over the same data, with no ETL in between. That convergence is why we took Milvus from a vector database to a Vector Lakebase. This talk walks through the workloads that forced the shift, and what the architecture looks like underneath.
- 16:35
Building a reliable, multi-region LLM gateway
Abstract
The LLM gateway has become a critical piece of infrastructure at Optiver. Engineers, researchers and agents rely on it daily for a variety of tasks, from analysing large volumes of market news and research to running automated workflows. When the gateway goes down, the impact is expensive and quickly noticed. Keeping LLM traffic running reliably across multiple regions and providers has been challenging, with many of the failures outside our control. In this talk, we share our experience building and scaling a multi-region LLM gateway. We walk through the key design decisions behind protocol translation, scaling, provider failover, observability and multi-region high availability, as well as the tradeoffs and footguns we encountered along the way.
- 16:40
Break
- 17:00
Nobody Planned AI Infra: How AI Builders Pushed a Database Beyond the Database
Abstract
AI builders keep asking for capabilities that stretch a database beyond its original boundaries: one database per agent, memory across sessions and state that survives disposable sandboxes. This talk follows the production needs that drove those changes, and the resulting choices around isolation, consistency, recovery and observability.
- 17:10
Break
- 17:25
Optimizing Organization-Wide LLM Inference Cost: Seat License, Pay-per-Token, or Provisioned, and Beyond
Abstract
Enterprises buy LLM inference through three structurally different pricing models: credit-based subscriptions, pay-per-token APIs, and self-hosted GPU capacity, with little guidance on which to use at a given volume or what signals it's time to switch. This talk introduces the Efficiency Curve: cost per token under the cheapest procurement mode at each volume, and its crossover points. Using a July-2026 pricing snapshot across three model quality tiers, I show a counter-intuitive finding: the subscription-to-API crossover often never economically materializes; a credit plan's idealized per-token rate can undercut every API price at scale, so the real boundary is a terms-of-service seat limit, not economics. The self-hosting crossover, by contrast, is a genuine price crossover, landing between roughly 360-899M tokens/month depending on tier, and it shifts with output-token share. I walk through the derivation and share a monitoring framework that ties each metric to the procurement decision it should inform, drawn from running AI infrastructure inside a regulated bank.
Rapid Fire · Model systems
17:25–17:45- 17:35
Reinforcement Learning at Scale on Agent Substrate: Orchestrating Millions of Sandboxes
Abstract
RL post-training for coding and agentic models turns every rollout into a sandbox: a fresh environment with a task image, a few commands, a reward, and teardown. A single training run can need Millions of these per hour across thousands of distinct images, with starts arriving in bursts of hundreds and lifetimes measured in seconds. This talk highlights what we learned running 1M sandboxes using an open-source harness on top of Kubernetes called Substrate, and all the various technological innovations in the stack - warm pooling, image acceleration, low latency scalable storage,microVMs, gVisor, golden snapshot and more. We cover the complete stack orchestration layers that make this work in state of the art Al labs including benchmarks and latency assessment.
- 17:45
Life of a Game Developer in AI era
Abstract
AI is systematically absorbing the technical core of game development. Code generation tools now produce gameplay scripts, shaders, and engine plugins from natural-language prompts, while AI pair-programmers handle debugging, refactoring, and unit tests autonomously. Procedural content pipelines driven by generative models build entire levels, NPC behaviors, and quest logic without manual scripting. Automated QA bots playtest builds around the clock, flagging bugs faster than human testers. Even optimization — memory profiling, performance tuning, cross-platform porting — is increasingly delegated to AI agents. The developer's role shifts from writing code to reviewing, orchestrating, and validating machine output. This paper examines which engineering tasks AI has already displaced and what expertise remains irreplaceably human.
- 17:50
Day 1 close
Afternoon · AI applications breakout13:45-17:00
- 14:05
Building a Personal Agent for Growth with YouMind
Abstract
Yubo shares how to use YouMind to build a Personal Agent for personal growth.
- 14:20
Trust Your Own Evals, Not the Leaderboard: What 10k+ Internal Agent PRs Taught Us About Adopting Open Models
Abstract
Every team picking a model right now is reading someone else's leaderboard. We stopped, and the reason was an accident of how we shipped. Harvey released its cloud agent platform to our own engineers before we shipped long-horizon agents to lawyers. Internally it has now driven 10k+ merged pull requests across our repositories. That internal deployment was not just a safety net — it became the eval set. Once you have thousands of real agent runs on your own workload, you can measure a model against the work you actually do, instead of trusting a public benchmark that was never scored on your tasks. That measurement is what makes it rational to move to an open model, or to fine-tune one, rather than simply hoping it holds up. This talk covers the infrastructure that made that possible, and the four places it broke first: - Durable runs: what happens to a long-horizon agent when the worker dies mid-task, and what we built so the run survives it. - Per-user agent identity: we started on a shared service account and lost the ability to attribute what an agent did. Retrofitting identity was expensive. - Information boundaries: enforcing ethical walls and leaving a reviewable approval trail when an agent acts on a user's behalf. - Context engineering: the case where adding context back made agents measurably worse — a result no external benchmark would ever have surfaced for us. I will show the failures next to the wins, with real numbers and the denominators included, and demo the platform live. Every pattern here is architecture and engineering method, not a product walkthrough.
- 14:35
Beyond the Pilot: Managing Your 500th AI Agent
Abstract
Getting your first AI application into production is hard; you hear that at every AI conference. But what happens when you're managing your 50th, 100th, or 500th agent? At enterprise scale, the challenges fundamentally change. It's no longer just about building agents that work. It's about managing hundreds of agents across teams, business processes, and systems while maintaining reliability, governance, visibility, and control. Who owns each agent? How do you monitor quality and performance? How do you prevent duplicated efforts, manage shared knowledge, and ensure that an expanding AI workforce remains trustworthy? Drawing on real-world enterprise deployments on Dify's AI Agent Management Platform, Andy Wang will explore what happens after AI agents successfully reach production. Topics such as the architectural decisions, operational challenges, and organizational lessons that rarely come up in conversations about pilots, but become impossible to ignore once you approach scale. The next frontier of enterprise AI isn't about how fast you build your first agent. It's about how effectively you manage your next 500.
- 14:40
Break
- 14:55
Beyond Reasoning: Building Infrastructure for AI Agents That Act
Abstract
AI agents are moving beyond reasoning and generation toward taking real-world actions on behalf of users. This shift requires a new infrastructure layer for identity, authorization, trust, credentials, and execution. Drawing on Visa’s work on Visa Intelligent Commerce (VIC), this session explores how these primitives are being designed for autonomous agents — how an agent proves who it is, demonstrates user intent, accesses credentials securely, and interacts with external systems safely. We’ll discuss the emerging infrastructure stack needed to move agents from assistants to trusted actors in the real world.
- 15:10
Beyond Screenshots: Building Agent-Native Verification for Mobile Apps
Abstract
As one of the founding Android engineers on Instagram Edits, this talk shares my first-hand lessons from making Instagram Edits on Android agentic. Agentic coding has dramatically accelerated development output, but human verification cannot scale at the same rate. We built agentic verification to close that gap. Today, our agents run 2,000+ verification workflows per week across agentic QA, developer feedback loops, stress testing, and debugging. I’ll share how we made a complex mobile app discoverable, controllable, and verifiable by agents, and how that enables a broader agentic mobile development loop that improves both developer velocity and product quality.
- 15:20
Agentic Harness: Real-Time Audio and Video AI Interviews
Topic subject to speaker confirmation
- 15:30
Break
- 15:40
Your Repo. Your Benchmark.
Abstract
Turn thousands of your company’s merge requests into benchmarks to improve your coding agent harness.
- 15:50
Trusted Context: Building the Layer Between Enterprise Data and AI Agents
Abstract
Most enterprise AI agent failures don't look like model failures. The model is fine. It just doesn't know which of four revenue tables finance actually uses, who owns it, whether last night's pipeline ran, or that one column was deprecated in March. That knowledge exists inside the organization - scattered across technical schemas, pipeline telemetry, business definitions, and org charts - and almost none of it reaches the agent. This talk is about assembling those four kinds of metadata into a single, model-agnostic context layer that agents can query, and what it actually takes to do that inside a large enterprise. I'll cover the architecture briefly, then spend most of the time on the parts that are harder than the architecture: deciding what context is trustworthy enough to serve, keeping it fresh, exposing it to agents over MCP, and the organizational work of getting teams to maintain context they never see themselves using.
- 16:10
The Harness Is the First Reviewer
Abstract
Over the past year we modernized ATLAS end to end, backend and frontend alike: the cohort design workbench the OHDSI medical research network has run for over a decade. The Java backend moved from Java 8 to Java 21 and Spring Boot 3: some 1,600 files, with a net 65,000 lines removed. The frontend is a ground-up rewrite in Vue 3 and TypeScript: 110k lines of source, gated on every pull request by coverage-enforced unit suites and an end-to-end fidelity check against the entire OHDSI Phenotype Library, running publicly at atlas-preview.ohdsi.org/atlas. The large majority of that code was written by coding agents, far more change than anyone could have read line by line. The platform and the verification harness are open source under the OHDSI GitHub org, end to end. On the frontend rewrite I directed, reviewed, and accepted every change. When acceptance cannot mean reading every line, verification has to live somewhere else. The harness became the first reviewer, and I will show what it is made of: specs as the unit of delegation, the legacy implementation as a behavioral oracle, E2E suites and type gates as the merge criterion, and screenshot-driven iteration in place of pixel opinions. I will walk one real feature end to end and show the failure modes the harness caught, the ones it did not, and what I would gate differently today. This talk is for engineers and leads who need to deliver more than their team can hand-write. You will leave knowing how to structure specs so agents can execute them, which verification gates can replace line review and which cannot, and how to tell whether your project fits this model (rewrites with a reference implementation) or does not. Live instance: atlas-preview.ohdsi.org/atlas. All code: github.com/OHDSI/Atlas3.
- 16:15
Break
- 16:35
Your Data Agent Needs More Than a Knowledge Graph -- From Semantic Layers to Executable Ontologies with Apache Ossie
Abstract
* Semantic Layer as Infrastructure for Data Agents * Apache Ossie: Starting from Metric Interchange * From Specification to Implementation * What Makes a Semantic Layer AI-Native? * Ontology on Top of Semantic Models * Datus + Dosi: Building Semantic Layers and Ontologies from Enterprise Context * An Open Semantic Layer for the Agentic Data Stack
- 16:45
From Idea to Viral Launch: How I Built a 3D Little Prince Game with AI
Abstract
The Little Prince: Across the Stars is a 3D story game built by one person with AI. This talk follows the project from adapting a familiar story into explorable scenes, through iterating on code, 3D assets and visual polish, to its public launch. Sac shares what worked, what did not, and what the process means for people creating with AI.
- 16:55
From Matching to Delivery: Scaling Creator Partnerships with AI
Abstract
Through a demo of AhaCreator’s brand and creator interfaces, Susan shows how AI advances collaborations from brief to content delivery. Examples include a customer exceeding US$500,000 in collaboration spend in a single month and selected trend-driven campaigns moving from idea to publication in three to five days. The session explores how responsibilities are divided between AI and people, and how actual prices, response times, and delivery records inform future creator selection and partnerships.
- 17:00
Breakout close
World models, physical AI & AI-native products
10:00-17:50 · UTC+8Main stage10:00-17:50
- 10:05
Welcome
- 10:25
Taxonomy of World Models
Abstract
“World Model” is a ubiquitous - and overloaded - term. Let’s explore how world models are used from simulation to visual understanding in the context of spatial intelligence and beyond.
- 10:45
HTML is all your agents need: Redefining Context Engineering
Abstract
general audience version: Most agent output still ends its life as text. We think that's a waste of a rendering engine. This talk shows how treating HTML as an agent's primary output format turns model responses into videos, slide decks, and business artifacts that people can actually use — no bespoke renderer, no proprietary format, just the most widely trained-on markup language in existence. We'll walk through the architecture of an agentic system built around HTML as its visualization layer, what breaks at scale, and what we learned shipping this in production. We'll also introduce HyperFrames, our open-source, free framework for agent-generated visuals, and show how teams can drop it into their own agents today. technical audience version: Multimodal agents fail in ways text-only agents don't: the model can't see what it made, can't reliably locate things in a frame, and can't hold a long visual edit in working memory. This talk covers the context engineering techniques we developed at HeyGen to close that gap — asset naming conventions that carry semantics, contact-sheet and collage prompting for VLM review, frame numbering and grid overlays for spatial grounding, and HTML as an intermediate representation that keeps generation inside the model's training distribution. The underlying thesis: don't fight the distribution, reframe the problem into one the model already knows how to solve. We'll close with HyperFrames, the open-source framework where these techniques live.
- 11:05
AGI is decoding. Encoding is the moat.
Abstract
As AGI becomes more capable, where can vertical AI products build a lasting advantage? Drawing on her work in the beauty industry, Ying Yang distinguishes general models' decoding abilities from the work of encoding tacit industry knowledge, expert judgment and consumer needs into usable rules and data. She traces a bottom-up product path from consumer decision support to small brands, large brands and the upstream supply chain, exploring how AI can lower transaction costs and turn real demand into growth.
- 11:10
Break
- 11:25
AI in Manufacturing: The Last Mile Is Half the Journey
Abstract
AI now writes reports, reviews contracts and ships code, and demos have never been easier. Inside a factory, though, it meets decades-old equipment, a workforce with very different skills, judgment that lives on paper and in spreadsheets, and owners who ask what every investment returns. HICAP, a leading maker of liquor closures, spent the past two years putting AI into its own delivery, quality, planning and marketing. Shihui Zhu shares how a manufacturer picks AI projects by business impact, enters through specific agents, and brings AI into the execution, monitoring and feedback of everyday processes: the last mile of manufacturing AI, where ninety miles in is only halfway.
- 11:40
Trusting Evals I Can’t Read
Abstract
AI now writes more than we can check: code, tests, support replies, translations. We used to trust work because a human read it. Nobody can read it all now, and it ships anyway. I hit this in the smallest way possible: I'm building a voice agent that takes bubble tea orders in English and Mandarin. I live in Asia and speak Mandarin every day, like a kindergartener. I can't read or write it. So I can't read half of my own evals. You may read both languages fine. It doesn't help. The volume of changes means nobody reads everything, in any language. Picture what a bad judge costs: Light sugar becomes full sugar, the judge says "pass," and someone gets a bad drink. In a clinic, 十四 (fourteen) sounds like 四十 (forty). The bot hears the wrong dose, the judge says "pass," and someone gets hurt. Multiply that by every call nobody listens to. So I'm building trust as a loop, with Pipecat Evals and open models on one laptop. An LLM writes evals in both languages. A simulated customer orders, switches languages, and changes their mind. A local judge grades the call. Then the loop checks the judge: pass/fail rules I can read, planted bugs the evals must catch, a second judge from a different model family to flag disagreements, and a native speaker for the calls that matter. You'll leave with that loop, and one question for any eval: what would it take for this test to be wrong, and who would notice?
- 11:50
The Good, the Bad and the Ugly: What 3,000 live sessions taught us about streaming speech-to-text
Abstract
Speech-to-text seems like a solved problem. But when we looked at our own Mandarin practice sessions, we found something unexpected: about one in four had words in the transcript that were never spoken. A streaming model was inserting Korean, Hebrew, and Thai into Mandarin answers. We ran the same recordings through the model after the sessions, and the transcripts were almost perfect. The models that struggled with our audio also scored well on public benchmarks. To find out why, we built a replay rig and tested four models on real sessions. We switched the model we used in production, but that still didn’t explain everything. So we kept investigating. I’ll show you what we found, step by step, including the two settings that had the biggest effect on streaming transcription—and how much each one can improve results on your users’ audio.
- 13:15
Lunch · On your own
- 13:55
AI startups: products, markets & what comes next
Discussion topic subject to final confirmation
- 14:15
Stronger Models, Leaner Harnesses: What to Control and What to Let Go
Abstract
The same model can produce very different success rates, costs, latency and risk depending on its agent harness. Drawing on MiniMax Code, this talk examines how tool discovery, cache behavior and execution gates shape those outcomes. Two production examples cover discovering app tools at CLI invocation rather than injecting every tool on every turn, and using file timestamps to prevent writes before reads. The talk also asks which prompts and planning constraints can be removed as models improve, and which boundaries still need to be enforced by the execution layer.
- 14:30
Beyond Vision-Language-Action: First Principles for Building Physical AI
Abstract
Beyond Vision-Language-Action, the next generation of Physical AI requires a fundamentally different understanding of intelligence. While recent progress in VLA models has significantly improved high-level semantic reasoning and robotic policy learning, physical interaction with the real world remains constrained by limited perception modalities and simplified assumptions about embodiment. This talk revisits Embodied AI from first principles. Inspired by biological cognition and human sensorimotor systems, we discuss why future Physical AI must evolve beyond vision and language toward rich multimodal perception—including force, tactile sensing, proprioception, contact dynamics, and continuous interaction with the physical world. We further propose a layered framework for Physical AI, covering perception, cognition, world modeling, robot foundation models, action generation, data engines, simulation, and lifelong learning. Rather than treating these components independently, we argue that they should form a closed-loop embodied intelligence system capable of continuous adaptation through interaction. Finally, we discuss pragmatic engineering principles for deploying Physical AI in today’s industrial environments, outlining an incremental roadmap from narrowly specialized robotic applications toward more general-purpose embodied intelligence.
- 14:35
Break
- 14:50
From 3D Generation to World Models: Building Persistent Interactive Worlds for Physical AI
Abstract
AI has made rapid progress in language and 2D visual generation, but Physical AI requires something more fundamental: the ability to represent a persistent 3D world, understand how that world changes under actions, and interact with it over time. In this talk, VAST will share its technical evolution from 3D foundation models to world models. We will discuss how 3D generation is moving from high-fidelity visual assets toward native, pipeline-ready spatial representations, and how this spatial foundation can further evolve into persistent and interactive worlds. A key focus will be a world-model architecture that separates world state, state transition, and generative rendering. Rather than predicting only the next video frame, the model maintains a camera-independent 3D state and learns how that state evolves, enabling long-term consistency, controllable interaction, multi-view reuse, and real-time experiences. We will also discuss how internet video and engine-native synthetic data can be transformed into aligned 3D state and action data, providing a scalable path toward simulation and training infrastructure for Physical AI.
- 15:05
How We're Building Open Decision Models for On-Device Agents
Abstract
In mid-September, the release of Jev kicked off a new category of AI models: decision models. Instead of generating text, a decision model answers bounded questions (which tool to call, which route to take, whether an action is safe) and returns a typed answer with a calibrated confidence. In this talk, we'll cover what decision models are, why everyone is excited about them, and how they work. We'll then share how we're building open, multimodal decision models for the edge on top of our LFM architecture. We'll close with a live demo of a multimodal decision model running fully on-device.
- 15:25
Communication Among Sovereign Agents: The Foundation of Agent Economy
Abstract
Ten years ago, I shut down my personal agent company. It hit three bottlenecks: language, reasoning, and fulfillment. LLMs have largely solved the first two. Fulfillment remains, and it is not a technical problem but an economic one. That is why A2A and a dozen other protocols have not yet produced an agent economy. What's missing is a structure: many sovereign agents, connected by a communication layer that is agnostic to who owns an agent, which model or harness it runs on, and what actions it can take. Value moves at scale only when agents can propagate actions across each other's boundaries.
- 15:30
Break
- 15:50
Real2Real: A Quantum Embodied AI Paradigm for Optimal Behaviors Generation
Abstract
Exploring the Real2Real paradigm and Quantum Boltzmann Machines for sampling optimal behaviors grounded in real-world embodied intelligent agents.
- 16:05
Noe-0: A World Action Model Built on Real-World Human Experience
Abstract
This talk introduces Noe-0, Noematrix’s embodied intelligence pretraining model. Its World Action Model jointly predicts future video and robot actions, connecting world understanding with physical execution. We will present our Full-chain Zero-Teleop approach, which uses RoboPocket to collect real-world human manipulation data for both pretraining and task-specific post-training. The talk will cover key model design principles, representative robot demonstrations, and open research questions toward robots that can perform a wider range of everyday tasks.
- 16:20
Building Robot Hardware for Rapidly Evolving Models
Abstract
Robot hardware has traditionally focused on speed, payload, precision, and actuator performance. Yet as robot intelligence rapidly evolves—from imitation learning to VLA models, world models, and end-to-end approaches—hardware must adapt to changing software architectures while remaining reliable over years of deployment. Through the development of Taku, we explore this challenge from three perspectives: Reliable Foundation, Robust Interfaces, and Accelerated Iteration.
- 16:25
Break
- 16:40GL
- 16:50
From Hardware to Intelligence: Full-Stack Evolution and Real-World Deployment of Home Service Robots
Abstract
For home service robots to work reliably in complex, dynamic and highly unstructured homes, the mechanical body, perception, motion control, task planning, AI models, data feedback loops and engineering platform must work together. From joints, end effectors, sensors and force control to navigation, real-time control, task scheduling and cloud services, every part affects whether a robot can complete its task. In real homes, communication latency, motion accuracy, hardware-software integration, data quality, model generalization, long-horizon task stability, recovery from failures and remote operations all become challenges at once. Capabilities that work in the lab need continuous testing, system tuning and engineering iteration to adapt to different layouts, furniture, objects and habits. Drawing on these practical problems and lessons, this talk traces the full stack from hardware to intelligence and the work required to turn algorithms into stable, maintainable products that can keep improving.
- 17:00
Break
Rapid Fire · Data, memory & context
17:00–17:30- 17:10
Robot Data Needs a Build System
Abstract
Robot datasets grow not only by adding new episodes, but also by accumulating derived columns such as embeddings, labels and rewards as new models become available. Traditional approaches often require rewriting entire datasets and depend on fragile job orchestration. This talk applies build-system ideas to robot data: precisely tracking work that has not yet been computed, incrementally processing missing ranges, resuming interrupted jobs, atomically publishing results, and pinning data versions for reproducible training. With LanceDB, teams can continually update a robot’s understanding of historical data without repeatedly rewriting the raw data.
- 17:20
Memory Engineering, RSI and Team Knowledge Layer
Abstract
For the past year, our team has worked the way many teams are about to: each engineer driving a fleet of coding agents, with a shared memory layer underneath doing the remembering. This talk is the engineering report from that year, organized around one question: how much of your judgment can you formalize into environments and verifiers? Whatever stays informal, a human has to stay in the loop to provide. The question plays out at three scales. Personal: which 90% of conversations not to remember, and why forgetting is a feature, not a bug. Loop: self-improvement is bottlenecked by verification, not generation. Where the verifier is deterministic, the loop closes (DeepMind’s AlphaEvolve on Borg scheduling: a discovered heuristic, in production over a year, continuously recovering 0.7% of Google’s fleet-wide compute). Where the verifier is taste, humans hold the merge (Meta’s TestGen-LLM: three mechanical filters first, then engineers accept 73% of what remains). Organization: at night, human review bandwidth is zero, so what your agents can safely do overnight is exactly the judgment you have formalized. That, not model choice, sets the ceiling. Intelligence can be rented. Memory must be owned.
- 17:30
Reading the Web at Trillion-Token Scale
Abstract
How does Jina Reader turn the web into context for models? This talk follows its browser-rendering, snapshotting and cleaning pipeline, then uses real request distributions to show how a small number of very long pages can dominate token costs. It also examines the tension between anti-bot policies, anonymous API abuse and paid access as agents browse at scale, and explores alternatives such as agent-facing ads and verifiable tasks.
- 17:50
Closing ceremony
Exhibitor booths
Booth demos
- 10:25
Daytona
Sandboxes for AI agents, shown live: an agent runs hostile code safely, analyzes a 100k-row dataset, and ships a working web app to a public URL.
- 10:45
Sonar
Using SonarQube to Support AI Agent-Driven Software Development
- 11:05
Zilliz
How Vector Databases Reshape the Infrastructure for Generative AI
- 11:25
ClickHouse
An Introduction to Agent Observability with Langfuse
- 12:10
Stripe
Balancing Cost and Pricing: Monetization and Pricing Strategies for AI Products
- 13:45
Tonbo
yield your agentic workload on your laptop and resume it anywhere
- 14:15
You.com
Real-Time World Awareness for AI Agents: You.com Web Search API
- 14:55
StepFun
Beyond the Screen: Real-World Tasks with Step 5 Preview
- 15:15
百道 / Baidao Data
One Cloud. Full AI Stack.
- 16:35
Raytone
Code Offline: Raytone AIBox Live
- 11:45
Copula
Build AI's next challenge
Four sessions from Shanghai
All speakersRyo Luex-Cursor
When we can do anything, do we still know what we want?
Ying YangChiling Chuanyue
AGI is decoding. Encoding is the moat.
Marco CasalainaMicrosoft Core AI
Keynote · Live Demo
Christoph LassnerWorld Labs
Taxonomy of World Models
In the room
Conference photo albumBefore Shanghai
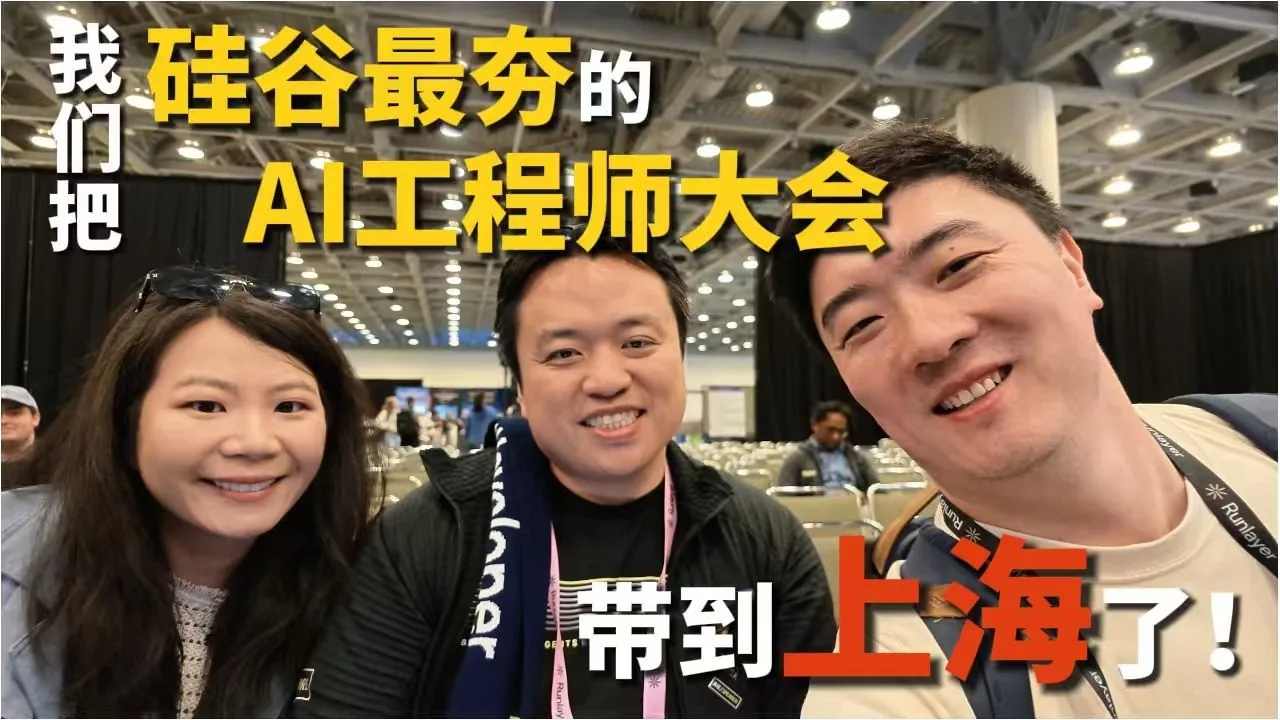
At AI Engineer World’s Fair · From left: Mengying Li, swyx and Yuzheng Sun
How AI Engineer came to Shanghai
Watch the Shanghai introduction ↗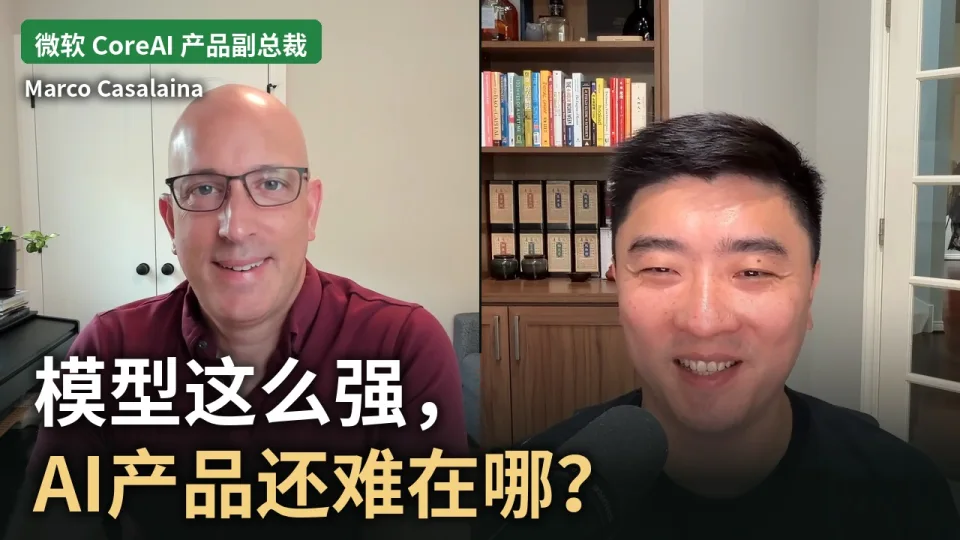
Pre-conference interview · Marco Casalaina and Yuzheng Sun · 43 min
Whose permissions should an AI agent have?
Start at 06:00 · Agent identity ↗What people took home
Shanghai community wallBETWEEN TALKS
“I realized I hadn’t taken a single photo with all the people I’d been talking to.”
FROM THE AUDIENCE
“Still, it's the best talk I saw on day 1 of AIE…”
THE DAY AFTER
“Seeing people share what they learned and who they connected with has been so rewarding.”