October 13, 2026Main stage4 min read

Shipping like a startup, regulated like a bank

David Abitbol describes Revolut’s move toward self-hosted coding models, the inference tuning that made them practical, and the operational controls used around a regulated engineering organization.

David AbitbolRevolutOps & Infrastructure Leader

From the conference livestream · 6:03:31–6:15:05 on YouTube. The player starts and stops at this session’s boundaries.

6:03:31 ↗

The engineering bottleneck was bigger than coding time

An engineer can write code faster and still spend days moving a feature toward deployment. David Abitbol opens Revolut’s AI story with two measures from a sample of about 2,000 engineers: coding time, measured in hours, and lead time from picking up a feature to having it merged and ready to deploy, measured in days.

Early use of Gemini helped with looking up information and reading documentation. Abitbol reports improvements in both measures. The initial rollout of Claude Code was less compelling economically: some engineers consumed substantial token budgets without a similarly clear return, so the company imposed limits.

That created a second problem. When tokens feel scarce, engineers save them for a difficult coding task instead of using them across the surrounding work. Abitbol describes self-hosting GLM models as a way to give engineers much more freedom to use AI without unpredictable bills.

He reports that the move to GLM 5.1 coincided with roughly 60% better coding time and 70% better lead time on Revolut’s chart. The internal comparison does not isolate the model change from other causes. His interpretation is that engineering delays include the inbox, Jira, Confluence, and other work around the code. Cheaper access broadens which tasks people are willing to delegate.

6:07:24 ↗

Tune the same GPUs before buying more

Open models became Revolut’s default for this workload, with frontier services kept available for exceptions. Abitbol reports using 56 B200 GPUs to serve GLM 5.3 to roughly 2,000 engineers. His target is a time to first token below three seconds; once it exceeds five, users start complaining. Around 200 tokens per second is adequate for the interactive workload he describes, especially as engineers increasingly launch tasks in parallel and return when they finish.

The economics he reports are a blended cost near $0.30 per million tokens and spending around a tenth of the prior Anthropic/OpenAI invoice. Those figures describe Revolut’s deployment and utilization, not a portable price for any self-hosted model.

Simply loading weights onto GPUs did not deliver the desired performance. The team tuned its serving system against actual demand. The chart below holds the GPU count constant while showing higher request volume and lower latency.
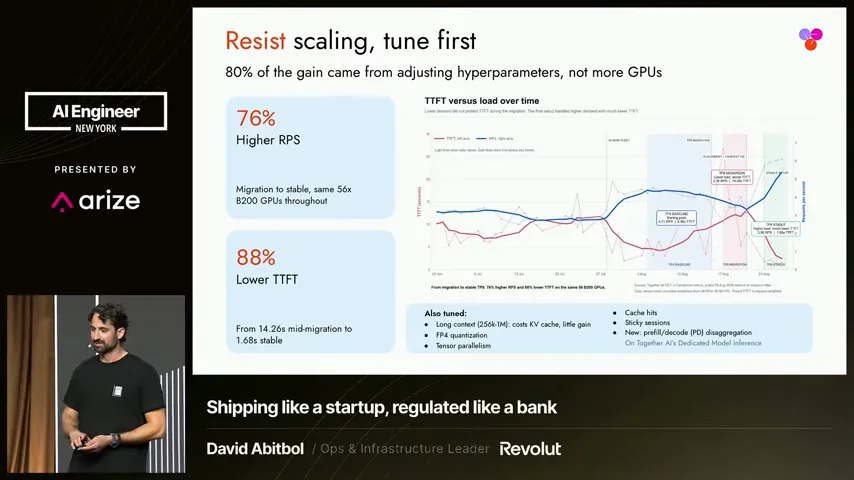
Revolut’s tuning slide reports 76% higher requests per second and 88% lower time to first token on the same 56 B200 GPUs.

At 6:10:16, the slide reports 76% higher requests per second and an 88% reduction in time to first token, from 14.26 seconds during migration to 1.68 seconds in the stable setup. Abitbol’s advice is to resist adding GPUs until the existing configuration has been tuned.

6:10:29 ↗

Context, cache, and the shape of inference

The context window competes with concurrent requests for GPU memory. The KV cache stores attention data from tokens already processed, so the model can reuse it while generating the answer. Reserving room for the maximum advertised context may waste capacity when most coding requests are smaller. Abitbol sizes the window to the work engineers actually send.

Quantization can reduce the GPU memory footprint. He favors FP4 on the Blackwell-generation hardware in this deployment. Tensor parallelism also affects the tradeoff: fitting the weights across four GPUs does not necessarily leave enough KV-cache space for the workload, so an eight-way configuration can perform better.

Cache reuse is especially valuable when coding tasks repeatedly carry similar context. He advises checking the cache-hit rate, then considering techniques such as speculative decoding and separating prefill from decode. Prefill processes the input context; decode generates the answer token by token. Their different workloads create opportunities to tune or separate the serving stages.

The production application still needs to handle capabilities outside the main model. For a text-only coding model, Abitbol suggests routing image understanding to another model rather than sacrificing coding quality just to keep every task on one endpoint. Compatible APIs then let engineers use their preferred coding harness against the hosted models.

6:12:47 ↗

Keep control around the model

Abitbol finishes with the operational case for self-hosting. Downloading weights and running them on infrastructure selected by the company is a different data path from sending inference requests to a model developer’s hosted service. The deployment choice matters more than the model’s country of origin alone.

He describes Revolut’s approach to human oversight: configure the sandbox and approval rules so restricted operations require intervention. The rules constrain what a coding agent can actually execute, rather than relying on a promise that a human will review everything later. He also discusses misuse by insiders and prompt injection as concerns for the surrounding controls.

His comments about regulatory classification and acceptable hosting locations describe his view of Revolut’s circumstances. They should not be read as a general determination that a model, region, or sandbox automatically satisfies another organization’s obligations.

The final requirement is observability. If an incident occurs, the team needs enough telemetry to inspect what happened and follow it through the system. That same data supports operational analysis during ordinary use. Lower inference costs let engineers use the model more freely. Sandbox rules limit what it can do, and telemetry lets the team investigate when something goes wrong. Self-hosting leaves Revolut responsible for all three.

Full transcript 202 timestamped passages

Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the original livestream.

6:03:31Hello everyone, welcome.

6:03:35My name is David.

6:03:37I lead AI operations at a company called Revolut.

6:03:42We have 15 minutes today together.

6:03:45we'll talk about high performance engineering and self-hosting open source model on dedicated GPU.

6:03:52How does that sound?

6:03:54Cool.

6:03:55So it's going to be a technical one, so bear with me.

6:03:59So maybe to start off, because I know this is the US and you may not know Revolut,

6:04:04quick words about our company.

6:04:07We're a digital bank in Europe.

6:04:09We have 80 million customers.

6:04:11We're live in 45 markets.

6:04:14with the most downloaded financial app in Europe for the last year.

6:04:19And as of July, we're Europe's largest private company.

6:04:25So we're doing okay.

6:04:29The emphasis of Revolut is shipping a lot of product,

6:04:32and so there's a high focus on engineering culture and excellence on that demand.

6:04:39And so we'll talk about that.

6:04:41So let's talk about some AI.

6:04:45We have a chart here.

6:04:47I'm going to see two lines.

6:04:48This is a sample of 2,000 engineers' performance over the last year.

6:04:54So the green line is going to be lead time.

6:04:56So it's going to be when an engineer picks up a feature

6:04:59until a feature is merged and ready to be deployed.

6:05:04The blue line is going to be coding time.

6:05:06So the green line is in days.

6:05:07The blue line is in hours.

6:05:11Just to reset the timeline in case people forget,

6:05:13because AI moves really fast.

6:05:16Claude Code came out around February 2025, right?

6:05:20And that's the Claude Code, Sonnet 3.7,

6:05:22the one that would delete your prod database, right?

6:05:25Not the safe cloud and codex that we have today.

6:05:28So bear in mind when we talk about adoption.

6:05:32So what you see on this chart is January 25,

6:05:35first introduced AI in the company, right?

6:05:38Gemini.

6:05:39First time people were able to use private data within AI.

6:05:44Around February, we started playing around with Claude Code, and then January is when

6:05:48we first launched Claude Code at scale.

6:05:52What you see is Gemini had 10% improvement in lead time, 20% improvement in coding time,

6:05:58so that's people no longer need to look at Stack Overflow and reading documentation.

6:06:03But then Claude Code, not so much impact at the time.

6:06:08So when we launched it, we were highly skeptical about the cost of AI.

6:06:12we were seeing engineers spend a thousand a month,

6:06:1510,000 a month with not so much ROI.

6:06:18And so when we launched it,

6:06:19we launched it with strict budget limits.

6:06:23And so we're looking at the next thing, right?

6:06:24So how can we provide limited tokens to our engineers

6:06:27so they can use AI guild-free for a fraction of the cost?

6:06:31And so we looked into open source.

6:06:34So around April 26 is when we started

6:06:37self-hosting open source model.

6:06:39We're a big fan of GLM for coding.

6:06:41so around that time what you see

6:06:43April 26th, GLM 5.1

6:06:47we see 60% improvement

6:06:48in coding time

6:06:5070% improvement in lead time

6:06:53so traumatic impact

6:06:56what do we learn from this?

6:06:57well there's more impact on the lead time

6:06:59than on the coding time

6:06:59so what we find is the bottleneck for engineering

6:07:02is not necessarily coding

6:07:05you can save a lot of time

6:07:06not having to dig through your inbox

6:07:08or messing with Jira and Confluence

6:07:10and so when you have a limited token you're free to do that. You no longer have to save

6:07:16your tokens for the end of the quarter or the most difficult task. So where do we stand?

6:07:24Well open source is now a priority, a revolute, and your economics are favorable, the billing

6:07:30is flat, we don't have any bill shock any of the month, and the frontier is the exception.

6:07:35So obviously we keep using codex, code code.

6:07:38The latest model are fantastic.

6:07:40Jimmy and I are going very good as well.

6:07:43But we keep them as exception.

6:07:47So how do we get there?

6:07:51Some metrics that matter when you're self-hosting model.

6:07:54So to serve 2,000 engineers, we roughly need 56 B200.

6:08:00And that's to host GLM 5.3.

6:08:02GLM is a big model, right?

6:08:048.500 billion parameters.

6:08:07What you want to aim for is

6:08:09sub-3 second time to first token.

6:08:13This is empirical evidence.

6:08:15As soon as you exceed 5 seconds,

6:08:18my Slack inbox starts to blow up,

6:08:19and so we know that's the limit.

6:08:22In terms of throughput,

6:08:23it doesn't really matter as much.

6:08:24We serve, in terms of interactivity,

6:08:27200 tokens per second.

6:08:29People are fine.

6:08:29You don't need to go higher.

6:08:31The way people work has changed.

6:08:33which we no longer look at the stream of thinking tokens.

6:08:36People run tasks in parallel

6:08:37and check in when the task is done.

6:08:40But if you're in a high throughput

6:08:41and you're an engineer at Revolut,

6:08:43you just connect after 5 p.m. when one is on GPU

6:08:46you can get 800 TPS and then, you know, it's a dream.

6:08:51In terms of cost, in terms of impact,

6:08:53self-hosting, GLM, or blended cost of token

6:08:56is 30 cents per million.

6:08:58And so our invoice is one-tenth

6:09:00of what we were spending on Anthropic and OpenAI.

6:09:08So there's a lot of tuning

6:09:10that goes into running open source models.

6:09:14If you just get GPUs and upload weights on a GPU

6:09:19and you start doing some inference,

6:09:22you're going to get terrible performance.

6:09:24That's because your workload is going to be very dependent

6:09:28on the parameters that you set.

6:09:30So if you look all the way to the left of that chart, the blue line is going to be demand,

6:09:34so that's request per second.

6:09:35That's going to be what's going to be the bottleneck for your latency for your GPUs.

6:09:40And the red line is what we're optimizing for, that's the time to first token.

6:09:45So when we started back in April, you could see request per second around 3,

6:09:51which is high but not so high, and time to first token over 10 seconds, which is very slow.

6:09:58All of the data that you see is

6:10:00the same number of GPU. We did an increase GPU count with LLF56.

6:10:05And by the end, you see in August, requests per second were over 7, and time to first occur, and we're around 1.6.

6:10:12So we've had 88% improvement in performance for 76% increased demand.

6:10:19So the learning from this is there's a lot of parameters that you can improve on, and you really need to resist scaling.

6:10:25if you're looking to self-host a model.

6:10:28So let's talk parameters.

6:10:31There's no secret recipe,

6:10:33but the things you consider are the following.

6:10:37First one, long context is a scam.

6:10:40You really need to be mindful that

6:10:42even though you can serve one million token,

6:10:45256 is really what you need.

6:10:49Quantization, if you're running Blackwell generation GPU,

6:10:52you don't want to run anything higher than FP4.

6:10:55And the FP4 is best, roughly going from FP4 to FP8

6:11:00is a 40% saving in GPU footprint for zero loss in precision.

6:11:08Other parameters to consider, tensor parallelism,

6:11:10even though GLM fits on TP4, you don't have enough KV

6:11:14cache, and so maybe a TP8 works better,

6:11:16depending on how large your workload is.

6:11:20and then on the more esoteric

6:11:22check your cache hit

6:11:23coding test needs to be above 90%

6:11:25cache hit

6:11:27and you can look into optimize

6:11:30spec decoding

6:11:31sequential pre-fill, PD disaggregation

6:11:33all of these

6:11:36cool

6:11:37so now let's talk about production setup

6:11:41GLM obviously

6:11:41is a text only model

6:11:43which is a limitation for some people

6:11:46the trade off I would say

6:11:47we would make every time is get the smarter model and figure out how to do

6:11:51image recognition another way. You can easily have a local router, open codex is

6:11:56one, where you would route any image recognition to Gemini or Luna and keep

6:12:03GLM for the main task. If you really need some vision model, GLM 5G flash works

6:12:11really well. We have our UI designer making great use of it. Turnaround for UI product has gone a

6:12:20really, really long way. And then the last one is going to be about the harness. So all of these

6:12:29endpoints are going to be OpenAI compatible API with response API. And so you can use them

6:12:35inside OpenCode Codex, Codex app as well, works very well.

6:12:40And so that's what we recommend.

6:12:46And then last message, this one is for the CIO in the room.

6:12:52There's been a lot of stigma in using Chinese open source model.

6:12:57So the thing to consider is you're not using

6:13:01inference, dedicated endpoint that goes to China.

6:13:03you're just getting the weights and putting them on a US-based service.

6:13:08So for data sharing side, this is totally fine.

6:13:13Revolut in particular, because we're an EU-regulated bank,

6:13:18we fall under the most strict regime in terms of compliance.

6:13:23so what we find that works is all of these coding tasks are not considered autonomous agents.

6:13:30They're always with a human in the loop.

6:13:32And so how do you give reassurance

6:13:34that you have a human loop?

6:13:36You start by creating a sandbox that guarantees that.

6:13:40And the sandbox means now if you've used Codex Claude Code,

6:13:43it has all of these features of approve for me.

6:13:46You just have to set the rules for the operations

6:13:49that you don't want to allow.

6:13:50So you can allow grep but not gradle, for instance.

6:13:53And that's gonna give confidence to your regulator

6:13:56that it's not an autonomous agent

6:13:58that needs different supervision.

6:14:02This sandbox also protects you from rogue use.

6:14:05You may have bad actors inside your company, and you want to shield for that.

6:14:09You'd be surprised what you find in a large company.

6:14:13And then the last one is prompt injection.

6:14:15Not so much a thing now, given how smart models are, but always a thing.

6:14:21In terms of data privacy, we spoke about it.

6:14:24As long as the data sits in one of the countries that are in the data equivalency framework,

6:14:29so US, EU, UK, Israel, you're fine, you can get your GPUs there. All of your inference provider

6:14:36or GPU provider are going to have zero data retention by default. And then the last thing

6:14:43you need is a very strong open telemetry so that if you ever have an incident, you need to be able

6:14:51to go deep and look at the logs.

6:14:54Also gives you some analytics.

6:15:00All right, thanks everyone.

6:15:01That was all for my talk.