Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the original livestream.
0:50:59Hey,
0:51:01All right, I precariously balanced my water over there.
0:51:04My name's John Feminella.
0:51:06I work on AI architecture and engineering at Two Sigma,
0:51:09which is a hedge fund here in New York.
0:51:11Before I get too far into things,
0:51:13I have a legal disclaimer slide that I have to show you
0:51:16that says two things.
0:51:18One, I promise not to sell or market or offer you any securities
0:51:21at any point in this talk.
0:51:23and two, everything in this is my own opinion
0:51:25and not the opinion of Two Sigma.
0:51:27Thanks for indulging me.
0:51:28If I don't say those magic words,
0:51:30the 5G microchips implanted in me will explode.
0:51:35So that slide is a good example, actually,
0:51:37of how our industry is regulated.
0:51:40And as a regulated company with lots of controls,
0:51:43I think one thing that's always interesting
0:51:45is to explore what happens when controls fail
0:51:47because that gives you a good idea
0:51:49about why the controls were there in the first place.
0:51:51And so I'd like to tell you a story about that by showing you another legal slide.
0:51:56After August 2020, a very interesting contract clause suddenly started showing up in a bunch
0:52:02of commercial loan agreements.
0:52:03And this clause essentially tries to prevent a certain scenario from happening.
0:52:07And it's complicated, but I'll explain it like this.
0:52:10Let's say that you're a lemonade stand business, and you borrow money from a lender to capitalize
0:52:15your lemonade stand.
0:52:16and the bank that's overseeing that transaction,
0:52:19that's in the middle between the borrower and the lender,
0:52:23sends the lender all of the money that you owe in a catastrophic mistake.
0:52:29You'd probably be mad and want the money back,
0:52:31but the lender might also say,
0:52:33no thanks, you paid us back and we're all good,
0:52:35so we'd rather keep the money.
0:52:37Something like this happened in August 2020.
0:52:40Revlon, the cosmetics company, had borrowed money under a big 2016 term loan.
0:52:45And that loan was split up into a bunch of pieces across 300-plus lenders, hedge funds, credit funds, CLOs, other banks.
0:52:53And in the middle is Citibank, the administrative agent.
0:52:56Being the agent in this kind of transaction means that you're performing the plumbing that connects the borrowers with the lenders and managing the lifecycle of the loan.
0:53:05So in this transaction, Revlon pays Citi, and then Citi pays the lenders.
0:53:09And Citi's not lending its own money.
0:53:10It's just in the middle, moving people's money around.
0:53:13So here's the plan for August 11th, 2020.
0:53:17Revlon would pay about $8 million of accrued interest to both groups,
0:53:21and the lender's principal would roll into this new facility.
0:53:24That's an exchange of paper, not cash.
0:53:27So the remaining lender's principal would stay put,
0:53:29and the idea here is that only interest should be going out.
0:53:33Principals should not be moving at all.
0:53:35And the bank had a piece of internal processing software called FlexCube.
0:53:40Isn't that a fun enterprise software name?
0:53:42in FlexCube, the easiest way to do this kind of transaction
0:53:46is to pretend to record it like Revlon were paying off the entire loan.
0:53:51And that triggers the correct interest payment calculations to everyone.
0:53:55You can probably guess what's about to happen next.
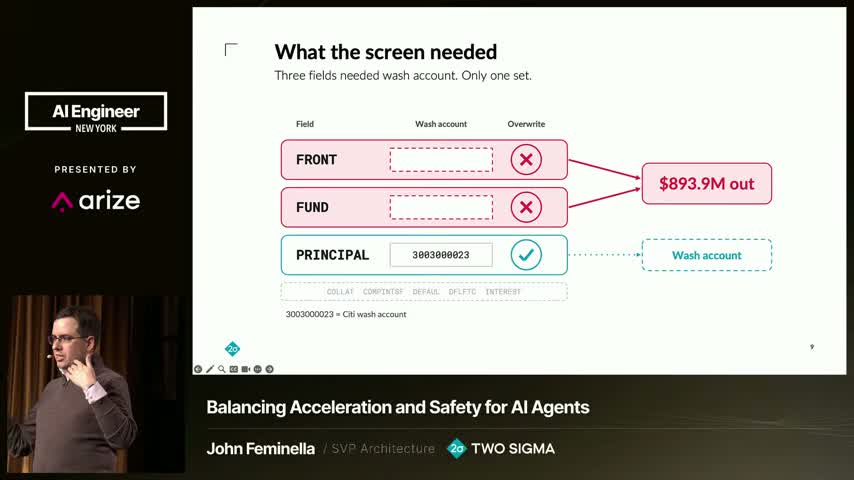
0:53:57So you're supposed to send the principal portion
0:54:00to an internal WASH account that you own as the bank
0:54:03so that it's booked and recorded correctly,
0:54:06but it never leaves the bank's perimeter.
0:54:08So keep your eye on that WASH account.
0:54:10What was supposed to happen is that the boxes labeled front and fund and principal should
0:54:16all include the WASH account number and should all have a check box checked next to them.
0:54:21So unfortunately it turned out that was what needed to happen, but for various arcane reasons
0:54:27the boxes were not checked.
0:54:28And although FlexCube pops up a warning notification that says, uh-oh, money is about to leave the
0:54:33bank, are you sure you want to do this?
0:54:35That was correct.
0:54:36Money was supposed to leave the bank because they were making the interest payments.
0:54:39So the three approvers who were supposed to approve that looked at it and said, yep, that's
0:54:44the right thing that's supposed to happen.
0:54:45And although that warning notification popped up, the human operators carrying out the transaction
0:54:50overwrote that.
0:54:52Remember, Revlon was making that interest payment.
0:54:54So the principal never went to the wash account.
0:54:56And instead, Flexcube sent the entire outstanding principal of the loan to all of the 300 lenders,
0:55:02about $900 million instead of $8 million.
0:55:06So every lender got the amount that they would have been owed
0:55:09if Revlon had paid the loan in full,
0:55:11but Revlon didn't want to pay off the loan.
0:55:13It wanted to hold on to its money.
0:55:14That was a great deal for the lenders,
0:55:15because remember, Revlon was in trouble at the time,
0:55:17so its loans weren't trading at face value,
0:55:19and getting all your money back on a deal
0:55:21that you thought was only worth 60 cents on the dollar
0:55:24is a great deal for you.
0:55:26So they didn't want to give the money back,
0:55:28even after Citi called them and said,
0:55:30please, that was a mistake, give us the money back,
0:55:32and their argument was,
0:55:32we shouldn't have to give the money back
0:55:34because you paid us in full, and that's how loans work.
0:55:37You eventually pay them back,
0:55:38and just because you paid it back at a different time
0:55:40than you were supposed to doesn't mean
0:55:41that we should have to give it back now.
0:55:43And so to prevent that from happening,
0:55:46commercial loan agreements everywhere started
0:55:47including a clause like that one.
0:55:49So what does a payment error at a bank
0:55:51have to do with AI agents?
0:55:53Well, the bank had this procedure, it had these controls,
0:55:56and everybody did what they thought the right thing to do was.
0:55:59That's the problem I want to talk about for the rest of this talk.
0:56:01Every day we're giving real agents real autonomy over systems like FlexCube.
0:56:06And how do we prevent accidents like that one from either from happening without locking everything down or just hoping we'll get lucky that they won't happen?
0:56:14So here's the crux of the issue.
0:56:16You can't really know in advance what an agent will do, right?
0:56:19There are these non-deterministic systems.
0:56:21And that sounds scary until you remember that humans are also non-deterministic systems and they're going to make mistakes too.
0:56:27And so most firms don't choose to say, well, in order to reduce the risk of humans making a mistake,
0:56:32we're going to lock them in rooms and prevent them from talking to each other,
0:56:34and they're all going to double-check everybody else's work.
0:56:36We allow them a certain amount of autonomy along with a certain amount of controls.
0:56:41So we give them boundaries, visibility, and we equip them with systems and controls
0:56:46that let them do their jobs effectively.
0:56:48So in this sort of model, safety and innovation are not opposite ends of a spectrum
0:56:52that you must trade off on.
0:56:53They're things that you can have at the same time.
0:56:56So I think you can have your cake and eat it too.
0:56:58And when we were thinking about what controls we wanted to apply to agents,
0:57:01we also looked at some approaches that didn't work for us.
0:57:04We don't want to sandbox or lock down everything,
0:57:06because a sandbox with no real access to systems is safe,
0:57:10but it's not very interesting or useful.
0:57:12If you let agents go wild and do whatever they want,
0:57:14that's maybe powerful and freeing from a cognitive perspective,
0:57:18but the isolation is very weak there,
0:57:21and that approach is generally not suitable for highly regulated enterprises.
0:57:25And then if you just have policy documents that agents look at or that are part of your
0:57:31specification for the prompt, that's also not very enforceable at runtime.
0:57:35You can't guarantee that that will be part of the enforcement controls.
0:57:38So what did work for us was thinking about what mix of controls would get us both safety
0:57:43and innovation at the same time.
0:57:45So how do we provide boundaries and stop problems but don't hinder folks from operating correctly?
0:57:51So we have a number of these controls, but today I'll talk about five of them.
0:57:55When I say controls here, what I mean are the guardrails and shared capabilities that let teams move in ways that don't hinder what they're trying to do.
0:58:04And we don't want to reach some chasm that we need to cross to let people get their work done and then make everyone wait while we build a bridge to get there.
0:58:15So these controls are composable.
0:58:17Each one does one job.
0:58:19And then together, they let us run agents with real autonomy at an appropriate level of safety.
0:58:26So the first problem is that agents were showing up everywhere.
0:58:29We have big teams with lots of agents running.
0:58:32We have small teams with a few.
0:58:33We have individual people running stuff in an uncontrolled way.
0:58:37And these come in every shape.
0:58:38Could be random chatbots.
0:58:39It could be MCP servers glued together in this Frankenstein hot
0:58:43podge.
0:58:44It could be cool notebook experiments.
0:58:46It could be really useful web tools for folks.
0:58:48But it's hard to answer when you look at that a few simple
0:58:52questions, like who owns this?
0:58:54what tools does it have access to, what should it be doing, what should it not be doing.
0:58:58And if you can't answer those kinds of questions, if you can't govern them,
0:59:01then you can't really also reuse that.
0:59:03So you're tempted to build multiple solutions to the same problem
0:59:08if you don't know about what exists already.
0:59:10And then the firm can't also govern those in any kind of legible way.
0:59:14So one thing the firms sometimes do here is add some kind of gate.
0:59:18Like don't let anything run until everything is registered and approved
0:59:21and has gone through this very onerous process.
0:59:24And that sounds safe, but if you look at what it does to the work,
0:59:27every idea, even some simple no-pick experiment,
0:59:30is going to wait in line behind something that's really risky.
0:59:34And we don't want to subject everybody who's given the diversity of agents
0:59:39to exactly the same process.
0:59:41So most people are going to give up,
0:59:42or they'll just get pushed to some shadow IT,
0:59:44less governed path that is less visible,
0:59:48and then we don't get to see anything at all.
0:59:50So that's what motivated the first control is an agent registry.
0:59:53You can't govern it, you can't see, so the agent registry makes agents legible, and it
0:59:57registers, retrieves, and discovers the key
1:00:00facts about agents that we want to know for any agent.
1:00:04So those are things like which tools it declares, what endpoints it's going to talk to, which product does it belong to, who owns it.
1:00:10And humans, other programs, other agents can then use the agent registry to decide what's available at the firm, whether that's useful for them, and to go use that as a source of truth for other questions.
1:00:23So this doesn't require extra effort on your part.
1:00:25It just happens when you use one of the firm's approved agent building frameworks.
1:00:29It's automatically registered.
1:00:30All that information is recorded there for you.
1:00:32And if you want to do a manual registration, you can certainly do that.
1:00:37So the second problem we have is that now that we've got all these agents doing all
1:00:42these things, we quickly notice that what they're doing is really different.
1:00:45And that means our agents carry really different risks, right?
1:00:49So a thing that summarizes Jira or linear tickets is really different than a production
1:00:55deployment agent that can touch a running system.
1:00:57And if we try to use the same review process to cover all of these agents, then every agent
1:01:03is waiting in the same queue for weeks for human review.
1:01:06And if people are going to route around slow processes, then we wind up in the same situation
1:01:11that we had before.
1:01:12So again, you might be tempted to say the answer is something like really detailed,
1:01:16heavy manual review by all of these different constituencies. Again, that feels safe, but now
1:01:21we've got a trivial summarizer waiting two months for the same sign-offs as an agent that is touching
1:01:27production systems. And most of the good agent ideas, most of the ones that have value right away,
1:01:33start out as small experiments, and you don't want those people to wait in the same line as the stuff
1:01:38that's touching production right away. So the reviewers are drowning in these low-risk requests,
1:01:43and the high-risk ones have to share that attention pool.
1:01:46So we don't want to trade away that speed if we can help it.
1:01:49So again, because not every agent needs the same review,
1:01:52and because most agents are purpose-built rather than open-ended,
1:01:56and when I say open-ended here,
1:01:57you can imagine coding agents like Pi or Claude Code.
1:02:00When you open them and you start typing,
1:02:03Claude Code or Pi doesn't know what you're about to ask.
1:02:06It doesn't circumscribe its purpose in any particular way.
1:02:09But most of the agents that are deployed in enterprises
1:02:12do have very specific purposes. When you're engaging with that agent, it's to do something
1:02:17specific that's well known and well understood. So they have a very specific reason for existing
1:02:21and a very circumscribed purpose. And you can tell these agents apart from each other by looking at
1:02:26what they declare up front, their tools, the endpoints they access, the controls that are
1:02:31applied to them, etc. So the third problem is that if you know about your agents and what they're
1:02:39doing, you'll quickly notice that many agents don't talk to each other.
1:02:43Sorry, they don't talk to just one thing or in just one capacity.
1:02:46The more open-ended the agent is, the more it looks like a Claude Code or Pi, the more
1:02:51it can do a variety and a diversity of different things.
1:02:55Call an internal API, run a tool like a web search, that sort of thing.
1:02:59And each one of those is a different opening, a different door to a different kind of risk.
1:03:03And if you give an agent an entitlement for a role account, then it can do a lot more
1:03:08damaged than something that's just going to read a public web page, for example.
1:03:12So the question is not, can this agent do X, but what's the granularity that we need
1:03:17to solve for for the agent to act successfully?
1:03:21And again, one tempting answer is to kind of be heavy-handed here, or to give every
1:03:25agent the same short allow list of stuff that's safe to do, and then block everything else.
1:03:31That's safe, but it's also useless.
1:03:33An agent that can't search, or can't call an API, or can't do any of those things without
1:03:38asking somebody first can't really do the work that it was intended for. And then
1:03:42teams either give up on those agents or they find a way around the wall and
1:03:46both outcomes are costly. So a wide kind of blanket block on everything trades
1:03:51away the innovation that we want to preserve and avoids making a real
1:03:55decision about risk. And as author John Shedd wrote, a ship and harbor is safe,
1:04:00but that is not what ships are for. So the fix here is to let agents declare
1:04:06their purpose upfront and say what tools they're going to use or what tools they
1:04:11need access to. So in the second column here we might say that a research
1:04:17summarizer is going to be allowed to use a web tool to access research, but for a
1:04:24release deployer agent we're not going to allow them to do that because they
1:04:28have no reason to use that tool. And so if they try to ask for it they won't get
1:04:32it by default. So we don't need to make this kind of decision for every tool.
1:04:35the agents just have to say which tools they want.
1:04:38And you're, as the agent author, you're in the best position to say,
1:04:42I need these four things out of the 500 that are available.
1:04:47So the way we need to enforce that is that when agents run in our managed environments,
1:04:52they look at the registry that we talked about before
1:04:55to look up what policies apply to it at initialization time.
1:04:59And that policy gets translated into enforceable statements,
1:05:02like which endpoints are you allowed to access, which hosts are you allowed to access,
1:05:07what other types of resources are available or not available to you.
1:05:10And in this way, nobody's writing a ticket every time they need to change the access.
1:05:15Nobody's going to talk to IT or some other group outside of your team.
1:05:20As long as you conform to the risk score that we talked about before
1:05:24and you're in the agent registry, you're governed, you're approved.
1:05:27So this is how we keep the cost to teams really low for deploying, building, running agents.
1:05:34And the same control architecture works in a variety of settings.
1:05:37The next thing we noticed was that teams were building a ton of different ways to evaluate agents,
1:05:42and every stack looks different, and some teams don't build anything at all.
1:05:45Sometimes you build this really detailed stack for how your models work.
1:05:49Sometimes there's nothing.
1:05:52And I think in general we'd be upset if teams were not writing unit tests, right?
1:05:58And we consider evals to be kind of the same thing.
1:06:00If models are changing, that's like a runtime dependency that your application has.
1:06:04And if your agent is going to change models, it doesn't know without the evals what's going to happen to its outputs and to the quality of those outputs.
1:06:14So, again, one tempting answer here is let's have some kind of central evaluation methodology
1:06:20that waits for a full eval suite and a committee sign-off.
1:06:24But now every prompt tweak, every one-line change is going to sit in that same queue.
1:06:29So we don't want to put more decisions on more reviewers for things like that.
1:06:34We don't want to trade away that iteration.
1:06:36So again, you wouldn't ship software without unit tests, so agents need evaluations for
1:06:40the same reason, and we want to provide the stuff at the level of the firm that's going
1:06:46to be the same for everybody.
1:06:47So Team A writing evals, Team B writing evals.
1:06:50They're both going to have many of the same features.
1:06:52So we want to have one shared approach to how we do evals, and have the shared approach
1:06:57be something that's run by the firm and available to everybody for doing their evals.
1:07:01So that covers all the common parts of evals, and all you've got to do is just write what's
1:07:06true about your agent.
1:07:09And finally, maybe you've had the experience of being asked to approve lots and lots of
1:07:13individual agent actions when there's a human in the loop.
1:07:16So that's fine on a small scale, but once you're operating agents in parallel or in
1:07:20production, this becomes completely onerous and review requests come in faster than anybody
1:07:26can be expected to approve them.
1:07:28After the first few times this is happening, you succumb to review fatigue where you just
1:07:32see yes, yes, yes, yes, yes.
1:07:33and eventually you click yes on something that's activating a nuclear bomb.
1:07:38So you don't want to click yes by reflex, but that's going to happen inevitably.
1:07:43One recent example of this is earlier this year, a director at an AI research lab
1:07:47told her open claw agent to suggest emails to delete from her inbox and wait for her approval.
1:07:52But her inbox was so large that eventually the agent compacted its context
1:07:56and lost the part that said, wait for my approval.
1:07:59And then it deleted hundreds of emails and didn't stop when she told it to stop on her phone.
1:08:04So again, you might be tempted here to make a human approve every action, but that's not
1:08:07the right way to do it.
1:08:09A better approach is to let these independent, conservative classifiers make decisions about
1:08:15routine calls, and then send a person only the requests that are most important, the
1:08:20ones that are most likely to make a difference.
1:08:22If you're saying yes, 99.99999% of the time, then that's probably just a rule that the
1:08:28agent should follow, not a request you need to ask the human for permission for.
1:08:31and the stuff that's unclear or ambiguous or potentially dangerous, yes, surface that to a human,
1:08:36or if it's definitely just dangerous, deny it outright. So this is a way to not have to do all
1:08:43the review work all the time. So we want to take the same approach for both explicit,
1:08:48when explicit rules apply, we want deterministic fast paths. When explicit rules don't apply and
1:08:54there's some ambiguity, we want a classifier to do that work instead. So putting those five pieces
1:08:59back together. You create a registry so that every agent is visible from the day it's created.
1:09:04You score each agent so human review goes in the right spot. You run agents on guardrails so that
1:09:09they only touch what they need. You share evals and metrics so everybody is reaching the same bar
1:09:14without having to reinvent the wheel. And then finally you govern your runtime to make sure that
1:09:18classification happens there and not somewhere else. So each of these controls works together.
1:09:24So I'll leave you with one question.
1:09:26Why do cars have brakes?
1:09:28It's not just so that you can stop, it's so that you can go fast and stop safely.
1:09:33So controls for our agents work the same way.
1:09:35Thank you very much.
1:09:37I'm John Feminella, and I hope you had a good time.