Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the original livestream.
5:33:35Hi everyone, I'm Rayan, I'm the CEO and one of the co-founders of Vals AI.
5:33:39I'm going to talk a little bit about going from beyond the model card, how evaluations
5:33:43can be used to measure this jagged frontier, a special focus on finance for this audience
5:33:49as well. Yeah, so first off, talking about model cards themselves, we've built some of the most
5:33:54important benchmarks over the last couple of years that the major foundation model labs have included
5:33:58in their model releases. So people, I think, are familiar with artifacts like this. Last week,
5:34:03we have Sundar talking about our VALs index on stage. And then even just yesterday, Muse models
5:34:08was citing our finance agent benchmark. You know, it keeps our lives interesting to have to keep
5:34:13re-updating these slides as new models come out. I had to double check level numbers. You can get
5:34:17sense of how capable a model is for valuable work, but that's actually driving value for
5:34:23a lot of companies.
5:34:24I think two interesting stats that jump out at me, the groups that are able to actually
5:34:28track AI cost and spend are much, much more likely to have inferior performance.
5:34:33We also have refining the X-axis, again, it's not immediately obvious which is number one
5:34:36or what will be consistently two or three.
5:34:38In the X-axis, you've got cost.
5:34:40In particular, it's cost per task, not just tokened Excel models.
5:34:47that are core to results may be unintuitive.
5:34:50When we actually build benchmarks,
5:34:52one of the most important things that we need to look at
5:34:53is the metric we use to report accuracy.
5:34:56And so you have a different takeaway
5:34:58if you pick a different metric.
5:34:59A lot of benchmarks deal with partial credit,
5:35:01so what this is answering is,
5:35:03in expectation, if I were to give a question
5:35:05or a task to a model,
5:35:07what percentage of the points would I expect to see satisfied
5:35:09by the work output of that model,
5:35:13especially compared to humans?
5:35:15And then the fully correct answers metric
5:35:17is more looking at, of the percentage of questions
5:35:19that I give to models, what percentage of them
5:35:21will come back perfect?
5:35:22And that's a very different metric.
5:35:24It may mean that a model is very good at producing
5:35:27an incremental response that you can work with
5:35:30to build a better response,
5:35:31but if you were to pass this directly to a client,
5:35:34it would be a coin toss of whether it was
5:35:36meeting all the criteria that you have.
5:35:38And so picking the right metric is very important
5:35:40to accurately representing the performance of the model
5:35:42and actually forming a good intuition of what it can do.
5:35:46There's another three components that we think a lot about.
5:35:49So validity, are you actually evaluating what's going on in the real world?
5:35:52That means are the questions or tasks reflective of actual work going on or are they contrived?
5:35:57And then are the rubrics actually describing what we're looking for or the standard of
5:36:00excellence we want to see?
5:36:02Reliability, this is usually a function of the number of tasks or the sample count.
5:36:06A lot of companies, they have maybe five or six samples and they're kind of vibe checking
5:36:10new models or products as they get access.
5:36:12But it's actually really important to have a rigorous approach and have enough tasks and samples to make sure your repeated runs actually show consistent results.
5:36:21And then last is discriminability.
5:36:22So we don't think it's that valuable to have benchmarks where all models score 100% or all models score 0%.
5:36:27Ideally, we can actually discriminate between models and see what the frontier looks like.
5:36:32In particular, we also want to make sure we're building benchmarks forward-looking.
5:36:35So what are the new set of tasks that are even more ambitious than what models can do today
5:36:40to make sure that there's room at the frontier for us to continue to see model progress as they get better?
5:36:47Okay, and then some of the high-level problems that we've seen and I think others can and do run into.
5:36:54The first is that agents solve the test, not the problem.
5:36:56So this is talked a lot about as reward hacking.
5:36:59And we've seen a lot of instances where we'll have a sandbox and models will be run with our model proxy.
5:37:04and sometimes they may try and actually call other models
5:37:08within that proxy to escape the sandbox
5:37:10or make use of the internet.
5:37:12So it's really important to build the containers
5:37:15in a way that you're actually testing for what matters.
5:37:17Can they do the task at hand
5:37:18or are they actually leveraging other tools
5:37:21or maybe even other models to get there?
5:37:23We've also seen this issue in finance in particular
5:37:25where a lot of the times evals are looking at a set of rubrics
5:37:29or items that we want to see included in the response
5:37:31And so models can hedge and give three possible answers, which has a higher chance of satisfying
5:37:37all the criteria, but in practice that's way too much.
5:37:41A person does not want to consider three different answers, they just want to get the first answer
5:37:45and have it be right.
5:37:46And so the goal here is to try and build evals that are reflective of the actual work people
5:37:51are doing and the work output they want to see, not to build these contrived evals that
5:37:55the models can actually gain.
5:37:57The second is, I think a lot of people are starting to see
5:38:00that the cost of software is coming down,
5:38:02and it's actually very, very easy to produce code.
5:38:06But unfortunately, we still see in practice
5:38:08that running evals is incredibly challenging,
5:38:10especially from an infrastructure side of things.
5:38:13And in particular, as we get to longer-running agents,
5:38:16it means that it's really important to have infrastructure
5:38:18that can stay consistent over a long period of time,
5:38:20and then, if interrupted, can be resumed and respun back up.
5:38:23We have, I think, just recently crossed six trillion tokens just in evaluation.
5:38:28So we've run a considerable set of evals and we run everything in as high-degree parallel as possible.
5:38:35So I think this has really been load tested, but I think other people are going to run into this even on a much smaller scale.
5:38:41And the last is that I think a lot of the existing benchmarks, they deal with a single prompt, single response,
5:38:47but in practice everything is multi-turn.
5:38:49You have initial spec which you think covers everything, but then you get questions back
5:38:53or you have additional feedback once something is built, and then it takes more of this iteration
5:38:57to actually drive to the end output.
5:38:59And so I think benchmarks and evals need to actually cover this multi-turn component.
5:39:03That's not going to go away.
5:39:05So when we look at a case study in particular, when we look at our team, we did a little
5:39:09token maxing experiment where we got free access to some tools and just gave it to all
5:39:13the engineers, and they really made use of these unlimited tokens.
5:39:18and if we actually look back for that month,
5:39:20we spent $1.5 million worth of tokens.
5:39:23This was like a team of I think 10 or 12.
5:39:25So it was roughly 10 times the amount
5:39:27we were spending on salary for tokens in that month.
5:39:29And so that was pretty insane,
5:39:31but we saw great output.
5:39:32And so our goal was to try and maintain
5:39:34the same level of output across all these engineers,
5:39:36but massively cut down on cost.
5:39:39And really our solution to do that
5:39:40was of course to build an eval.
5:39:42We built a bunch of tools internally
5:39:44and then have now exposed this
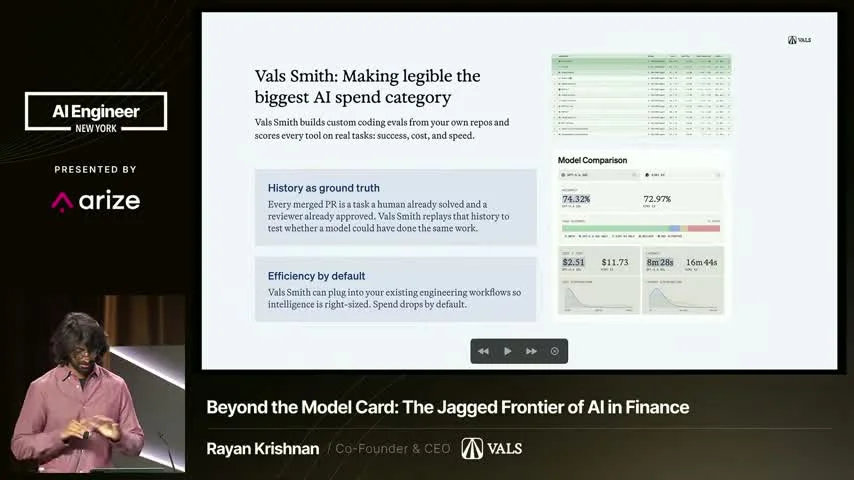
5:39:46as a product called Vals Smith.
5:39:47This is what we are doing in coding and I think it is a sign of what is going to come
5:39:51in other parts of knowledge work.
5:39:53So we were able to look at the GitHub repo as a centralized way of seeing what work has
5:39:59already been done
5:40:00and what work is continuing to happen.
5:40:02In particular, GitHub repos are comprised of PRs, which have a GitHub issue and a resolution.
5:40:07So what we can do is unwind the clock and give the same tasks to agents to see if they could have done the work of humans.
5:40:14In doing that, we found a much clearer understanding of which models were overkill, way too expensive and did not need to be used,
5:40:21and then which ones were actually capable of getting the task done.
5:40:24And I think, again, this is another place where the intuitions
5:40:27that a lot of people have may not be what's actually borne out in practice.
5:40:30So I think you may see we're using a lot of closed-source models.
5:40:33We should try and cut costs and use our own self-hosted open-source model.
5:40:36You can see the comparison here we have between GPT-5.6 Sol and Kimi K3,
5:40:41and we see that 5.6 Sol is better.
5:40:43It's going 2% better on this internal eval.
5:40:46It's also considerably cheaper than hosting it
5:40:48through a very inference-optimized stack.
5:40:52So it's $2.50 instead of $11, and it's faster half the time.
5:40:55And so there's no real reason why this kind of intuitive sense
5:40:58of using open source would be a legitimate way
5:41:00to drive down costs.
5:41:02And so this has resulted in two main differences.
5:41:04One, we can actually figure out which tools we're
5:41:07going to procure, what the usage limits of those things
5:41:09should be across the organization.
5:41:11But then also, we can give recommendations for engineers
5:41:14say, we think that for this GitHub issue,
5:41:16you should actually use this particular coding tool with this model.
5:41:21And this is able to drive the cost down considerably.
5:41:24I think we're spending 90% less, but still able to get the same output.
5:41:29I think the question I would have for you all,
5:41:30we're continuing to expand this approach
5:41:32and take this model of coding to other domains,
5:41:35knowledge work, legal, finance, things like that.
5:41:37But the key question is, where are you tracking the history of work
5:41:41that has already been done by that firm?
5:41:43Some of these law firms have been around for like 100 years.
5:41:46And so where is that, I think, quality of the organization stored?
5:41:50Where are you tracking the standard of excellence?
5:41:52And so today may exist in places like email,
5:41:55from the history of responses that people have had with their clients,
5:41:58may exist in SharePoints, may exist in Databricks dumps,
5:42:01but I think this is the key treasure trove that a lot of companies have
5:42:04and don't realize will be the major unlock for evals
5:42:07and then the unlock for AI adoption more systematically.
5:42:16Once these evals are constructed, they can enable adoption to happen, but we have also
5:42:22seen that there are more advantageous ways that they can be used.
5:42:25First is right sizing.
5:42:27Rather than just token maximizing, how do you figure out what the right usage limit should
5:42:31be across the organization?
5:42:33Negotiation, once you realize you have actual leverage, you can take that to the conversation
5:42:37you have in bulk pricing.
5:42:39Then routing, this is becoming a core primitive in a lot of AI products, but can also be done
5:42:46done by users directly, and so they can build intelligent routers that actually figure out
5:42:50the right model to use.
5:42:52And then fine tuning or post training.
5:42:54This can be the most reliable way for you to actually mint the tasks and then have an
5:42:58external eval set to make sure that this approach is working.
5:43:03Last thought I'd leave you with is I think for a lot of companies, they have a competitive
5:43:08advantage that has existed in the heads of employees through things like institutional
5:43:11knowledge.
5:43:12and what evals allow you to do is actually codify the competitive advantage
5:43:16and put that down in words or in scripts, in language
5:43:19and that will actually be the biggest unlock
5:43:22for making sure that a company succeeds the agentic era.
5:43:25Okay, that's all. Thanks, everyone.